Inference is bottlenecked by memory, not compute
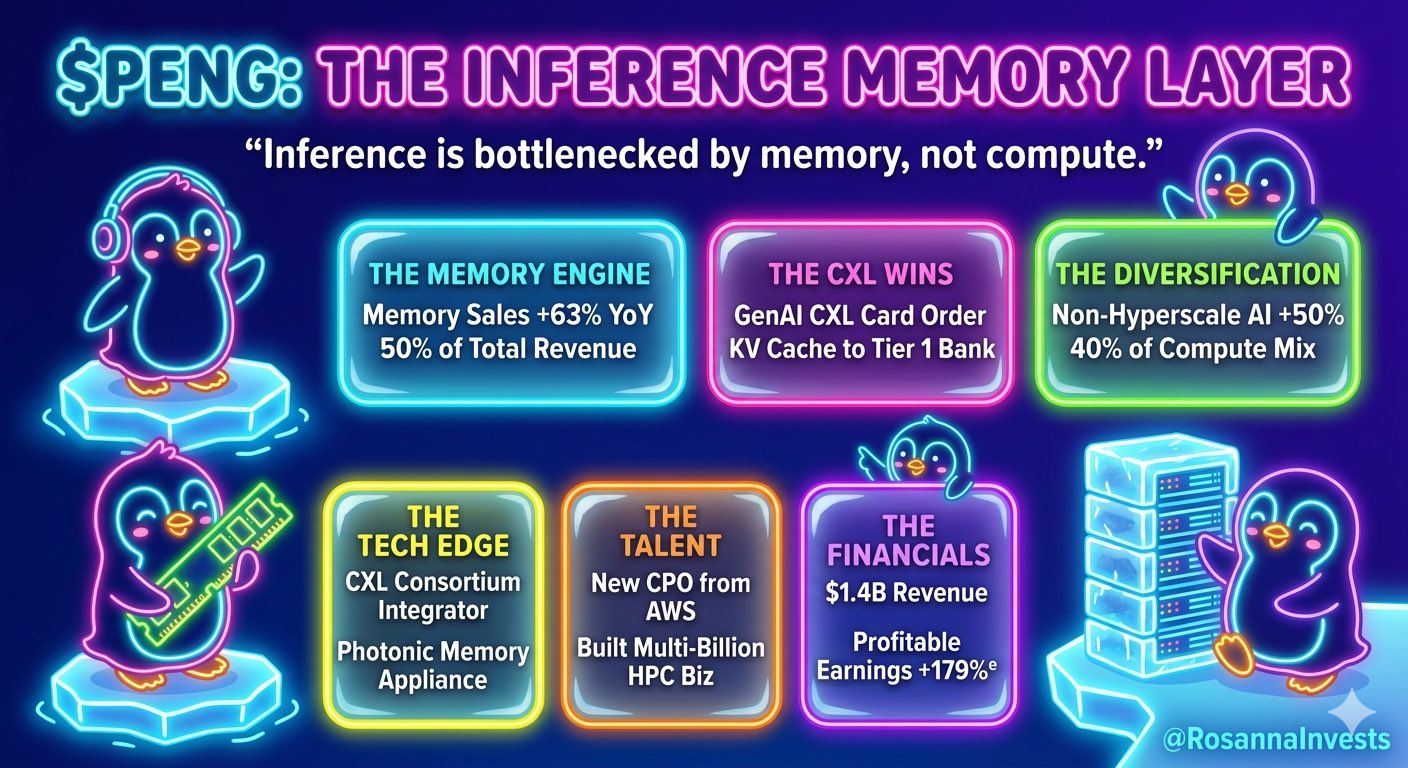
Inference is the next phase of AI, and inference is bottlenecked by memory, not compute.
Training gets the headlines because it demands giant clusters. Inference is different: it is the recurring work of serving models to real users, agents and applications. Every request needs fast memory close to the GPU, and every delay in moving model weights and context becomes a limit on throughput.
That changes where to look in the stack. The market is starting to price the GPUs. It has not yet priced the memory layer underneath themthe hardware, systems and integration that keep inference fed instead of waiting on data.
The key question for investors is not simply how many accelerators a data center owns. It is how efficiently those accelerators can be kept busy. Memory bandwidth, latency and capacity determine how many tokens a system can serve, how quickly it responds and how much revenue each deployed model can support.
Penguin Solutions ($PENG) sits in that less glamorous layer. The opportunity is not a claim that one ticker owns all memory. It is the broader thesis: as AI moves from training experiments to always-on services, bottlenecks migrate toward the components that move and manage information.
That is why the next AI trade may look less like a race for the biggest processor and more like a hunt for the constraint beneath it. Compute gets attention. Memory decides whether compute earns its keep.